
Jukatrashy
Add a review FollowOverview
-
Sectors Accounting
-
Posted Jobs 0
-
Viewed 27
Company Description
Breaking down The DeepSeek-R1 Training Process-no PhD Required
DeepSeek just made a breakthrough: you can train a design to match OpenAI o1-level thinking utilizing pure reinforcement learning (RL) without using labeled information (DeepSeek-R1-Zero). But RL alone isn’t best – it can result in challenges like poor readability. A mix of approaches in a multi-stage training repairs these (DeepSeek-R1).

—
The launch of GPT-4 forever changed the AI market. But today, it seems like an iPhone 4 compared to the next wave of reasoning models (e.g. OpenAI o1).
These “reasoning designs” introduce a chain-of-thought (CoT) thinking phase before creating an answer at inference time, which in turn improves their reasoning performance.
While OpenAI kept their techniques under wraps, DeepSeek is taking the opposite technique – sharing their development openly and earning appreciation for remaining real to the open-source objective. Or as Marc stated it best:
Deepseek R1 is one of the most amazing and excellent developments I’ve ever seen – and as open source, a profound gift to the world. This open-source reasoning model is as excellent as OpenAI’s o1 in jobs like mathematics, coding, and logical thinking, which is a big win for the open-source neighborhood … and the world (Marc, your words not ours!)
As someone who invests a great deal of time working with LLMs and assisting others on how to utilize them, I chose to take a better take a look at the DeepSeek-R1 training process. Using their paper as my guide, I pieced everything together and simplified into something anyone can follow-no AI PhD needed. Hopefully you’ll find it helpful!
Now, let’s begin with the basics.
A quick guide
To much better comprehend the foundation of DeepSeek-R1, let’s cover the fundamentals:
Reinforcement Learning (RL): A model finds out by getting rewards or charges based on its actions, enhancing through trial and mistake. In the context of LLMs, this can include traditional RL methods like policy optimization (e.g., Proximal Policy Optimization, PPO), value-based approaches (e.g., Q-learning), or hybrid methods (e.g., actor-critic methods). Example: When training on a prompt like “2 + 2 =”, the model gets a reward of +1 for outputting “4” and a penalty of -1 for any other response. In contemporary LLMs, rewards are often determined by human-labeled feedback (RLHF) or as we’ll soon learn, with automated scoring approaches like GRPO.
Supervised fine-tuning (SFT): A base design is re-trained utilizing identified information to carry out better on a specific task. Example: Fine-tune an LLM utilizing an identified dataset of customer assistance concerns and answers to make it more accurate in managing common inquiries. Great to use if you have an abundance of labeled information.
Cold start information: A dataset used to help the model get a general understanding of the task. * Example: Fine-tune a chatbot with an easy dataset of FAQ sets scraped from a site to develop a fundamental understanding. Useful when you don’t have a lot of identified information.
Multi-stage training: A model is trained in phases, each concentrating on a specific improvement, such as accuracy or alignment. Example: Train a design on general text information, then refine it with support knowing on user feedback to enhance its conversational capabilities.
Rejection sampling: A technique where a design produces multiple possible outputs, but just the ones that meet specific requirements, such as quality or significance, are chosen for more use. Example: After a RL process, a design produces a number of actions, however only keeps those that are beneficial for retraining the model.
First model: DeepSeek-R1-Zero
The group at DeepSeek wished to prove whether it’s possible to train an effective thinking model using pure-reinforcement knowing (RL). This kind of “pure” support finding out works without labeled information.
Skipping labeled data? Looks like a bold move for RL in the world of LLMs.
I’ve learned that pure-RL is slower upfront (trial and mistake takes time) – however iteliminates the costly, time-intensive labeling bottleneck. In the long run, it’ll be faster, scalable, and method more efficient for building thinking designs. Mostly, because they learn by themselves.
DeepSeek did an effective run of a pure-RL training – matching OpenAI o1’s efficiency.
Calling this a ‘substantial achievement” seems like an understatement-it’s the very first time anyone’s made this work. Then once again, perhaps OpenAI did it first with o1, however we’ll never ever know, will we?
The greatest concern on my mind was: ‘How did they make it work?’
Let’s cover what I learnt.
Using the GRPO RL framework
Traditionally, RL for training LLMs has actually been most effective when combined with labeled information (e.g the PPO RL Framework). This RL method employs a critic model that’s like an “LLM coach”, offering feedback on each transfer to assist the design improve. It assesses the LLM’s actions versus identified information, examining how likely the design is to be successful (value function) and guiding the model’s general strategy.
The challenge?
This method is restricted by the identified data it uses to assess decisions. If the labeled data is insufficient, prejudiced, or doesn’t cover the complete range of tasks, the critic can just provide feedback within those restraints – and it won’t generalize well.
Enter, GRPO!
The authors utilized the Group Relative Policy Optimization (GRPO) RL structure (developed by the same team, wild!) which removes the critic model.
With GRPO, you avoid the ‘coach’- and the LLM moves are scored over numerous rounds by utilizing predefined rules like coherence and/or fluency. These models find out by comparing these ratings to the group’s average.
But wait, how did they understand if these guidelines are the ideal rules?
In this method, the guidelines aren’t perfect-they’re just a finest guess at what “great” looks like. These guidelines are designed to capture patterns that typically make sense, like:
– Does the response make good sense? (Coherence).
– Is it in the best format? (Completeness).
– Does it match the basic style we expect? (Fluency).
For instance, for the DeepSeek-R1-Zero design, for mathematical tasks, the design might be rewarded for producing outputs that adhered to mathematical principles or logical consistency, even without understanding the precise answer.
It makes sense. and it works!
The DeepSeek-R1-Zero model had great efficiency on thinking standards. Plus it had a 86.7% of pass@1 rating on AIME 2024 (a prestigious mathematics competition for high school students), matching the performance of OpenAI-o1-0912.
While this seems like the biggest breakthrough from this paper, the R1-Zero model didn’t come with a couple of difficulties: bad readability, and language blending.
Second design: DeepSeek-R1
Poor readability and language mixing is something you ‘d anticipate from using pure-RL, without the structure or format offered by labeled information.
Now, with this paper, we can see that multi-stage training can alleviate these obstacles. When it comes to training the DeepSeek-R1 design, a lot of training approaches were used:
Here’s a fast explanation of each training stage and what it was done:
Step 1: They fine-tuned a base design (DeepSeek-V3-Base) with countless cold-start information points to lay a strong foundation. FYI, countless cold-start data points is a small fraction compared to the millions or perhaps billions of identified data points typically needed for monitored learning at scale.
Step 2: Applied pure RL (similar to R1-Zero) to improve reasoning skills.
Step 3: Near RL merging, they utilized rejection tasting where the model created it’s own identified data (artificial information) by selecting the very best examples from the last effective RL run. Those rumors you’ve found out about OpenAI utilizing smaller sized model to generate artificial information for the O1 design? This is generally it.
Step 4: The new synthetic information was combined with monitored information from DeepSeek-V3-Base in domains like writing, accurate QA, and self-cognition. This action guaranteed the design could learn from both high-quality outputs and diverse domain-specific understanding.
Step 5: After fine-tuning with the brand-new information, the model goes through a final RL procedure throughout diverse triggers and circumstances.
This seems like hacking – so why does DeepSeek-R1 use a multi-stage process?
Because each step builds on the last.
For instance (i) the cold start information lays a structured foundation repairing concerns like bad readability, (ii) pure-RL establishes reasoning nearly on auto-pilot (iii) rejection tasting + SFT deals with top-tier training data that enhances accuracy, and (iv) another final RL stage guarantees additional level of generalization.
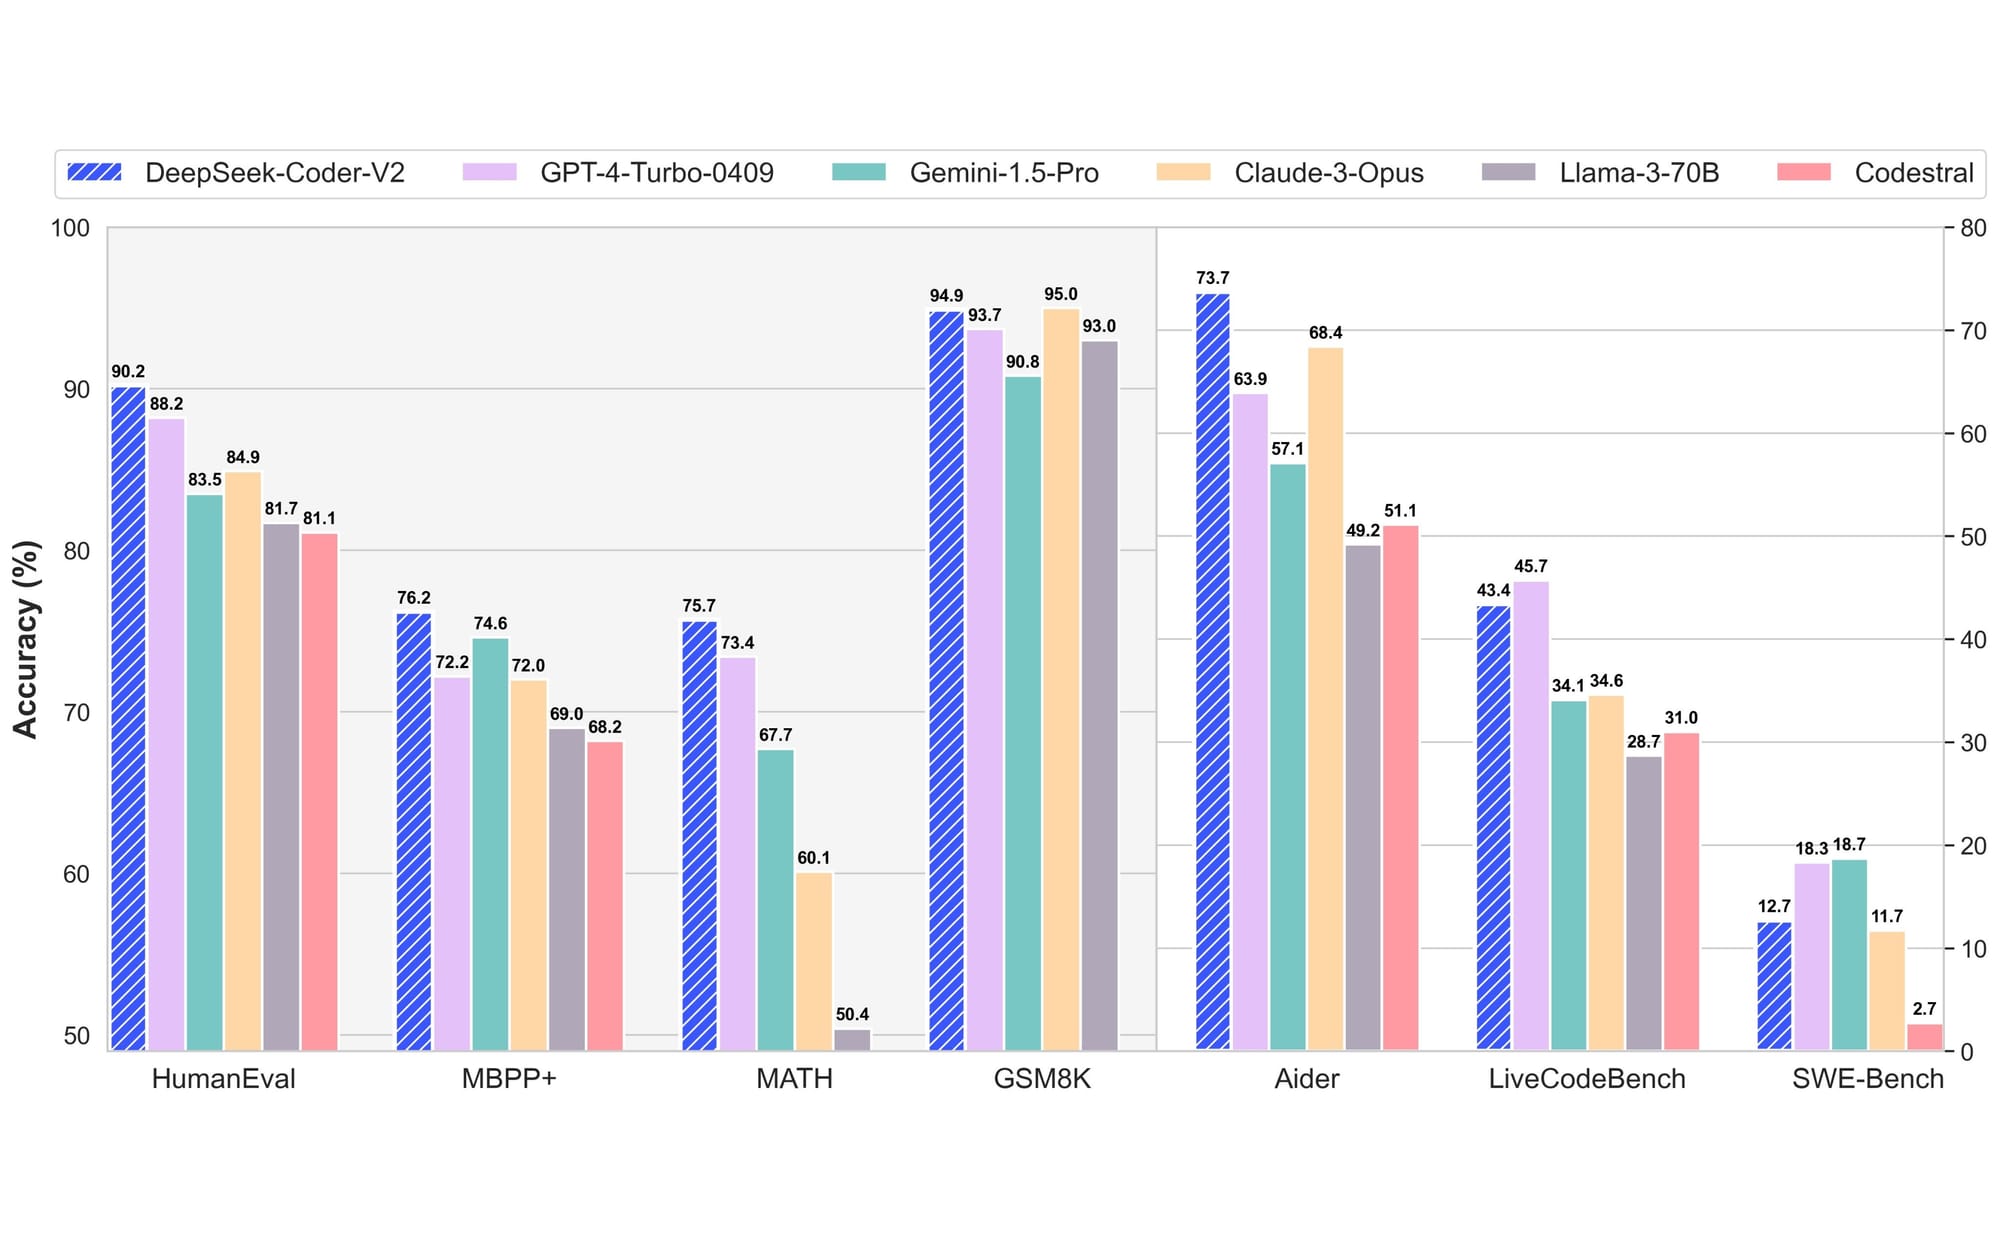
With all these extra steps in the training procedure, the DeepSeek-R1 design achieves high scores across all criteria noticeable below:
CoT at inference time depends on RL
To successfully utilize chain-of-thought at reasoning time, these thinking designs must be trained with approaches like support knowing that motivate detailed reasoning during training. It’s a two-way street: for the design to achieve top-tier reasoning, it needs to utilize CoT at inference time. And to enable CoT at reasoning, the design should be trained with RL methods.
If we have this in mind, I’m curious why OpenAI didn’t expose their training methods-especially considering that the multi-stage procedure behind the o1 design seems simple to reverse engineer.
It’s clear they utilized RL, produced synthetic information from the RL checkpoint, and used some monitored training to enhance readability. So, what did they really achieve by decreasing the competitors (R1) by simply 2-3 months?
I guess time will inform.
How to use DeepSeek-R1
To utilize DeepSeek-R1 you can evaluate it out on their free platform, or get an API key and use it in your code or through AI development platforms like Vellum. Fireworks AI also uses an inference endpoint for this model.
The DeepSeek hosted design, costs simply $0.55 per million input tokens and $2.19 per million output tokens – making it about 27 times more affordable for inputs and nearly 27.4 times more affordable for outputs than OpenAI’s o1 design.
This API version supports an optimum context length of 64K, however does not support function calling and JSON outputs. However, contrary to OpenAI’s o1 outputs, you can recover both the “thinking” and the real response. It’s also extremely slow, however nobody appreciates that with these reasoning models, because they open new possibilities where immediate responses aren’t the priority.
Also, this version does not support many other criteria like: temperature level 、 top_p 、 presence_penalty 、 frequency_penalty 、 logprobs 、 top_logprobs, making them a bit harder to be utilized in production.
API example with DeepSeek-R1
The following Python code demonstrates how to utilize the R1 model and gain access to both the CoT process and the last response:
I ‘d suggest you play with it a bit, it’s quite interesting to watch it ‘believe’
Small designs can be powerful too
The authors also show the thinking patterns of larger designs can be distilled into smaller models, leading to better performance.
Using Qwen2.5-32B (Qwen, 2024b) as the base design, direct distillation from DeepSeek-R1 exceeds applying just RL on it. This demonstrates that the reasoning patterns discovered by larger base models are vital for improving reasoning abilities for smaller sized models. Model distillation is something that is becoming quite an interesting approach, shadowing fine-tuning at a large scale.
The outcomes are rather effective too– A distilled 14B model outshines modern open-source QwQ-32B-Preview by a big margin, and the distilled 32B and 70B models set a new record on the thinking criteria among dense designs:
Here’s my take: DeepSeek just revealed that you can substantially improve LLM thinking with pure RL, no labeled information required. Even better, they combined post-training strategies to fix concerns and take efficiency to the next level.

Expect a flood of designs like R1 and O1 in the coming weeks-not months.
We believed design scaling hit a wall, however this technique is unlocking brand-new possibilities, meaning faster development. To put it in viewpoint, OpenAI took 6 months from GPT-3.5 to GPT-4.