
Spacepress
Add a review FollowOverview
-
Sectors Accounting
-
Posted Jobs 0
-
Viewed 26
Company Description
Open-R1: a Totally Open Reproduction Of DeepSeek-R1
Hey there! This blog site post is an introduction to the task, not a claim that we’ve replicated R1 yet. We’re constructing in the open, so as quickly as we have evaluation numbers, we’ll share them. You can follow our progress on Hugging Face and GitHub.
True, but it looks like there’s nothing to be examined as of right now. I assume the supreme objective is to train a brand-new reasoning model and then use the very same evaluation metrics as o1 and the DeepSeek-R1.
Well, there ought to be at least some sanity check and recognition to guarantee the design was trained correctly.
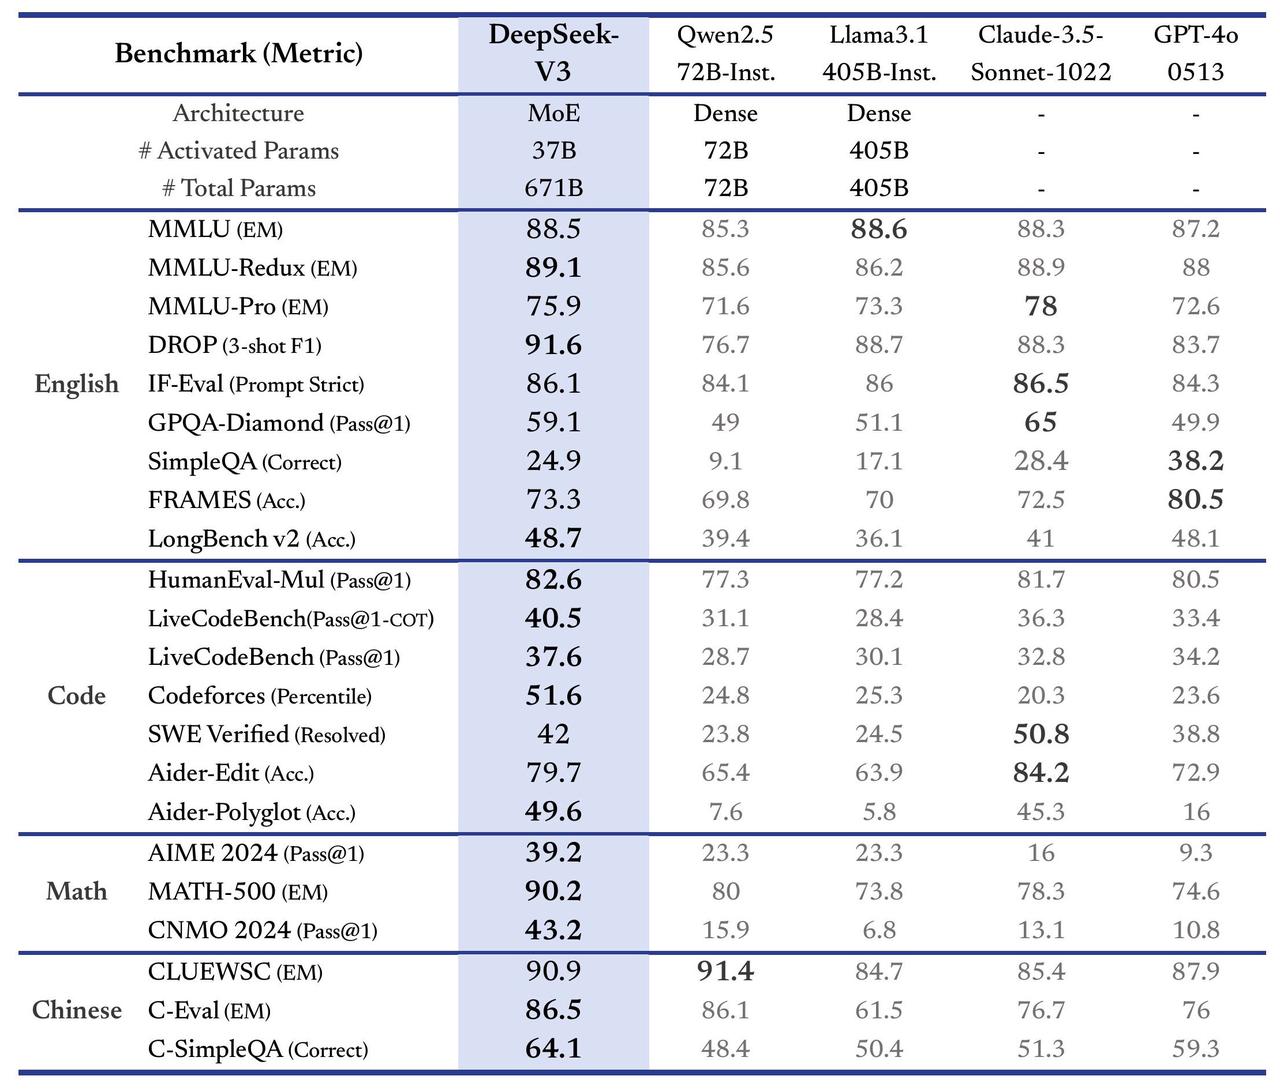
Oh yes, if you are discussing the evaluation variety of deepseek’s model it’s coming really quickly!
As pointed out in the blog site post there is no model called Open-R1 to check at all … not yet anyway. This is a blog site outlining that Hugging face will take the R1 Deepseek design, exercise how it was built as laid out in the paper and from what they released, and then duplicate that procedure.
in truth this is pretty much how science works … A comes up with a strategy, discovery or innovation and it is tested by B, C and D to see if it is reproduceable. Thats been the foundation of research now for a couple of centuries.
This blog site is not saying they have currently done so … Its a blog laying out an intent to start training a model like R1 and calling it Open-R1.
Also DeepSeek-R1 was just launched recently, and even in their paper they laid out the calculate hours needed. While those are low compute hours for a SOTA model this does not mean you can train stated model in a week. I ‘d personally enjoy to be able to train a transformer model in a week, however we may require to wait a while for that level of calculate technology.
So there are no criteria for a design that has not been constructed yet right? As laid out in the blog site, and again in reply to your concern.
However fear not, there is a GitHub Repo currently and contributors (hell I may join myself), some prelim work done, and a master plan. A great beginning position.
n
@edbeeching
has actually evaluated the released designs already
( src: https://x.com/edwardbeeching/status/1884273209136275742)
R1 just trained on o1 outputs, so collectively …/ s. This is what the brand-new AI czars are saying
Hi! This article is an introduction to the project, not a claim that we’ve recreated R1 yet. We will completely share the missing out on piece when we have them, you can anticipate the designs and datasets to be upload in this Hugging Face org and the code to be in this GitHub repo
That’s nice and essential to understand this incredible hype that lacks technical understanding and explanation. Science has to do with reproduction, and if they claim to be open, let them fullfill the open part.
Please do publish the training expense.
We will!

Excalidraw Hi n
@bojan2501
thanks, we will undoubtedly be working hard to make sure this training recipe can work for little language designs on consumer hardware given that not everyone has a cluster of H100s at home:-RRB- The tool we utilized for the images was Excalidraw! https://excalidraw.com
eagerly anticipating it! WTF are your speaking about?
must be a joke
It’s truly cool to see how the entire open source neighborhood comes together!
Ops …
5.5 M is number reporter in the deepseekv3 tech report (simply the training, not the experiment afaik), for R1 hard to approximate tbh however much less than 5.5 M imo
Historically, they have never ever launched code or datasets of their LLM training, so I wouldn’t expect this time to be different. If they would release it that would be amazing of course!
Yes of course!
So basically you’re asking to change existing censorship with another flavour of censorship?
The code for the designs are inside the design repositories, e.g. for V3: https://huggingface.co/deepseek-ai/DeepSeek-V3/blob/main/modeling_deepseek.py
Hello Team, I’m Ray Bernard, the author and developer of EQUATOR. My research team will be working on a paper concentrated on reproducing particular components of DeepSeek R1. Our objective is to reproduce the cold start and offer your group with a dataset that consists of COT and other methods to support these efforts. We like to contribute our work to help. Please let me know if you discover this beneficial. Best, Ray Bernard https://www.facebook.com/groups/1186310571520299/
Where is the examination numbers? without it you can’t call it reproduction.
8 replies
True, but it appears like there’s absolutely nothing to be evaluated as of today. I presume the ultimate goal is to train a brand-new reasoning design and after that utilize the same evaluation metrics as o1 and the DeepSeek-R1.
That’s quite interesting, I was asking myself why the questions the author exposed here are not being asked by others? I believe the work they have done is unforgettable but at the very same time I question why they would not put these missing out on pieces on if they are expected to be completely open.
Why even without reproduction and comprehension of the innovation they could affect so much the market in this way?
4 replies
Hi! This blog post is an introduction to the job, not a claim that we’ve reproduced R1 yet. We will absolutely share the missing out on piece when we have them, you can expect the models and datasets to be upload in this Hugging Face org and the code to be in this GitHub repo
Interesting read, and it is excellent that we see more effort into this direction: more optimization and less brute force.
Also question what tool did the author usage for developing step diagram.
2 replies
Excalidraw I’m so thankful that effort like this currently exist, I’m gon na attempt to contribute:-RRB- 1 reply
eagerly anticipating it! So racist articel
2 replies
WTF are your speaking about?
Awesome to have this open reproduction began!
For Step # 1 check out https://github.com/open-thoughts/open-thoughts!
https://x.com/ryanmart3n/status/1884284101265612856
Let’s do this thing!
1 reply
It’s actually cool to see how the entire open source neighborhood comes together!
Does anyone know the actual training expense of r1? I can’t discover it in the paper or the announcement post. Is the 6M cost reported by media just the number drawn from v3’s training expense?
2 replies
Ops …
Has anyone asked the DeepSeek group to publish their training information and code, or at least share them privately with an independent duplication project like this? Have they rejected such a demand?
A faithful replication depends upon using the very same dataset and hyperparameters. Otherwise, any major inconsistencies with the released criteria would be difficult to pin down-whether due to training data differences or the duplication approach itself.
1 reply
Historically, they have actually never ever launched code or datasets of their LLM training, so I wouldn’t expect this time to be different. If they would launch it that would be amazing of course!
In the meantime we have to make finest guess estimates and see if we can get there ourselves.
You provide great replication process of Deepseek thinking training. I will attempt something comparable to it.
This is really good details, can we tweak with particular use case when code is launched?
1 reply
Yes of course!
Please consider removing prejudiced, polluted or unaligned training information and make an effort to eliminate copyrighted works from the crawl from consumption. This will make the design more usable. If you reused anthropic checks, this may likewise help, get rid of obviouslybiased information will likely add a great deal of value. We don’t want another tainted, unaligned open source design, right? And no business would ever use deepseek or a model that reuses it, right?
We appreciate your work for the advantage of humanity, we hope.
Miike C from NJ
1 reply
So generally you’re asking to replace existing censorship with another flavour of censorship?
Can’t wait! Hopefully the design will be uncensored however whatever you can do is alright! Love seeing open source structure itself up. I’m not smart adequate to actually help but I can contribute support lol
Hello guys, I am even just looking for code for DeepSeek-V2, in order to completely understand multi-head latent attention. You do not seem to have code in Hugging Face even for that. Or am I missing something? Don’t see anything in src/transformers/models. MLA is not properly described in their paper, so it would be crucial to have code for this.